Meet 
Plan it, drive it, arrive together.
Your whole crew, moving in real time — on the phone in your hand or the screen in your dash.
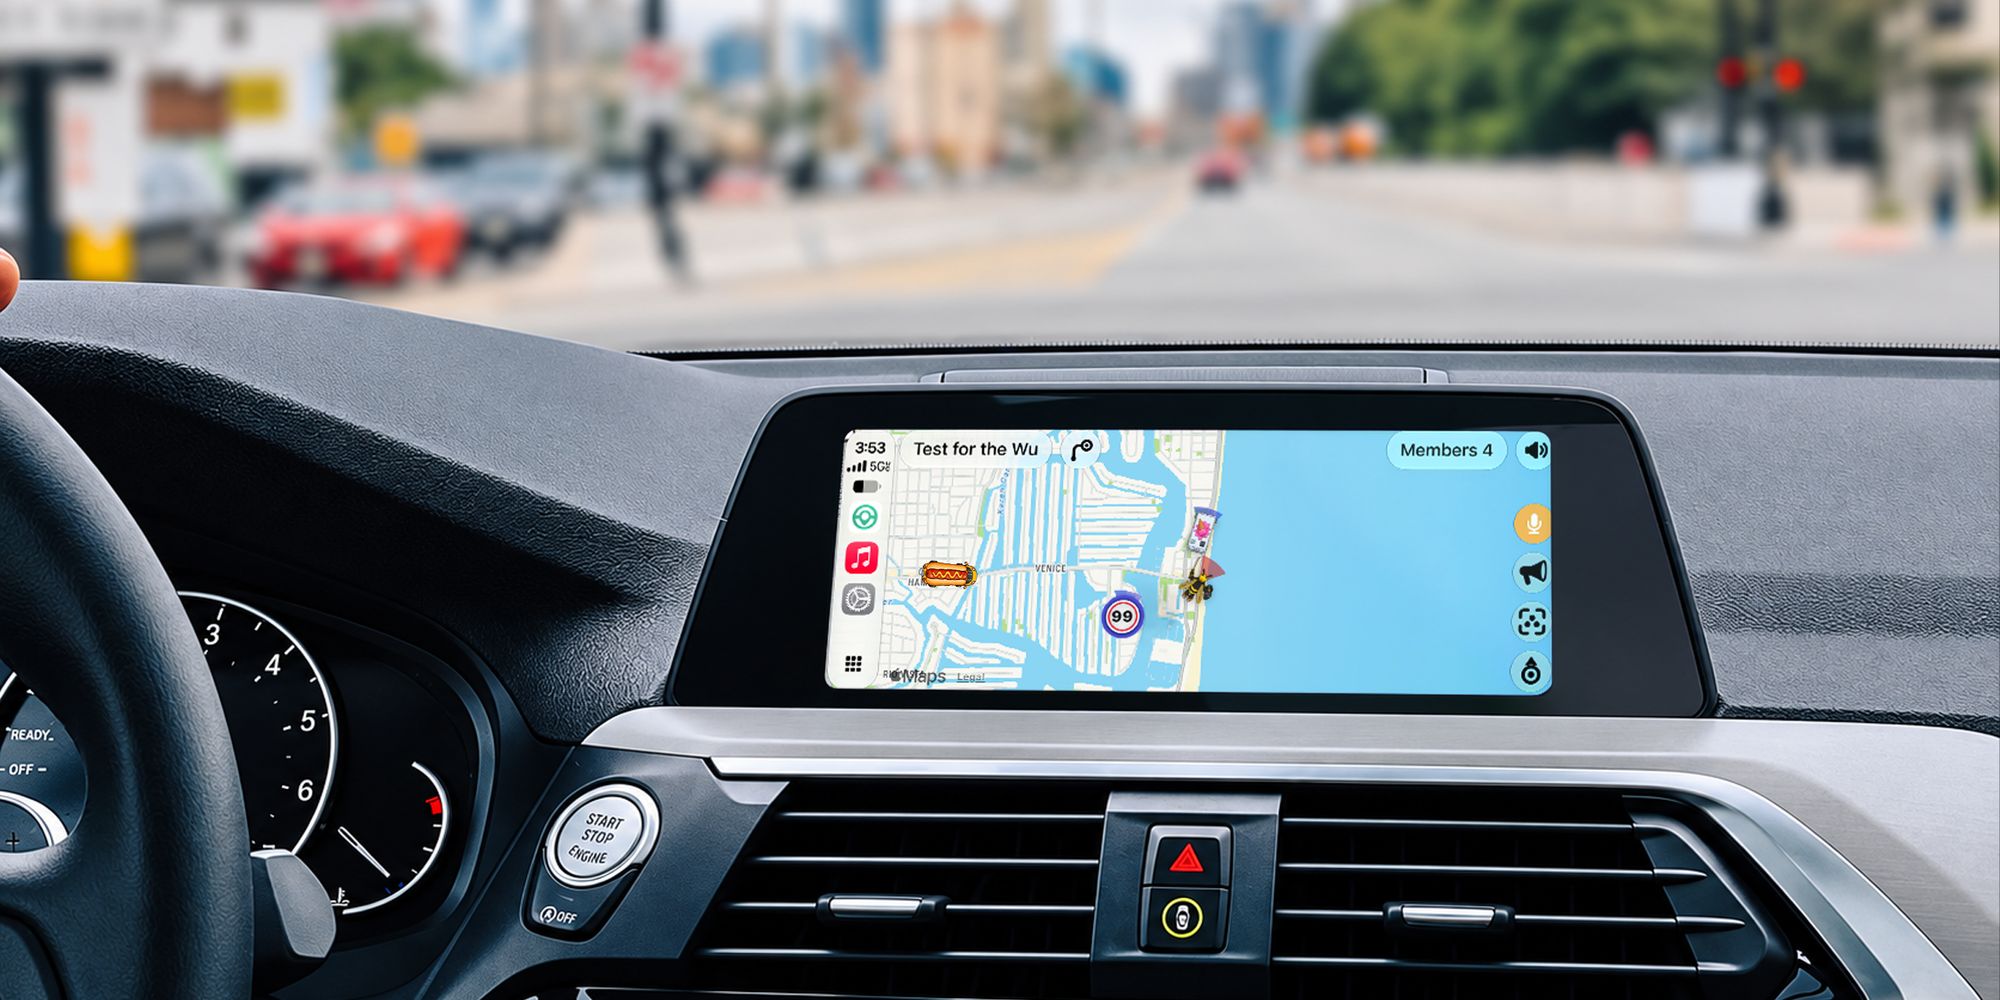
Push‑to‑talk to one car or the whole convoy. Hands stay on the wheel.
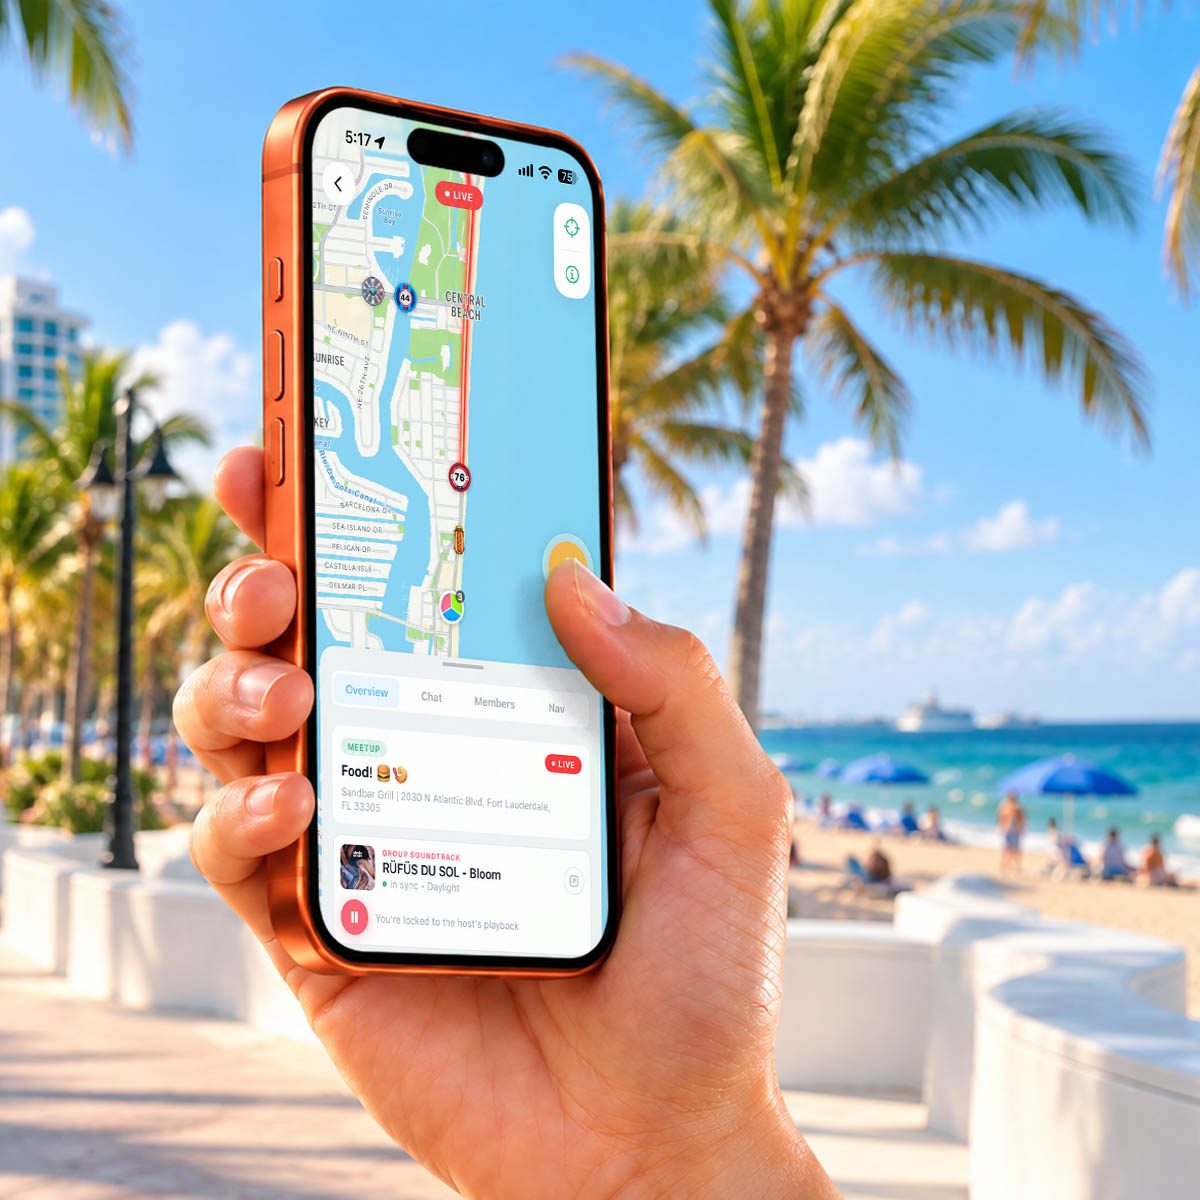
The host picks the playlist. Everyone hears the same beat at the same moment.
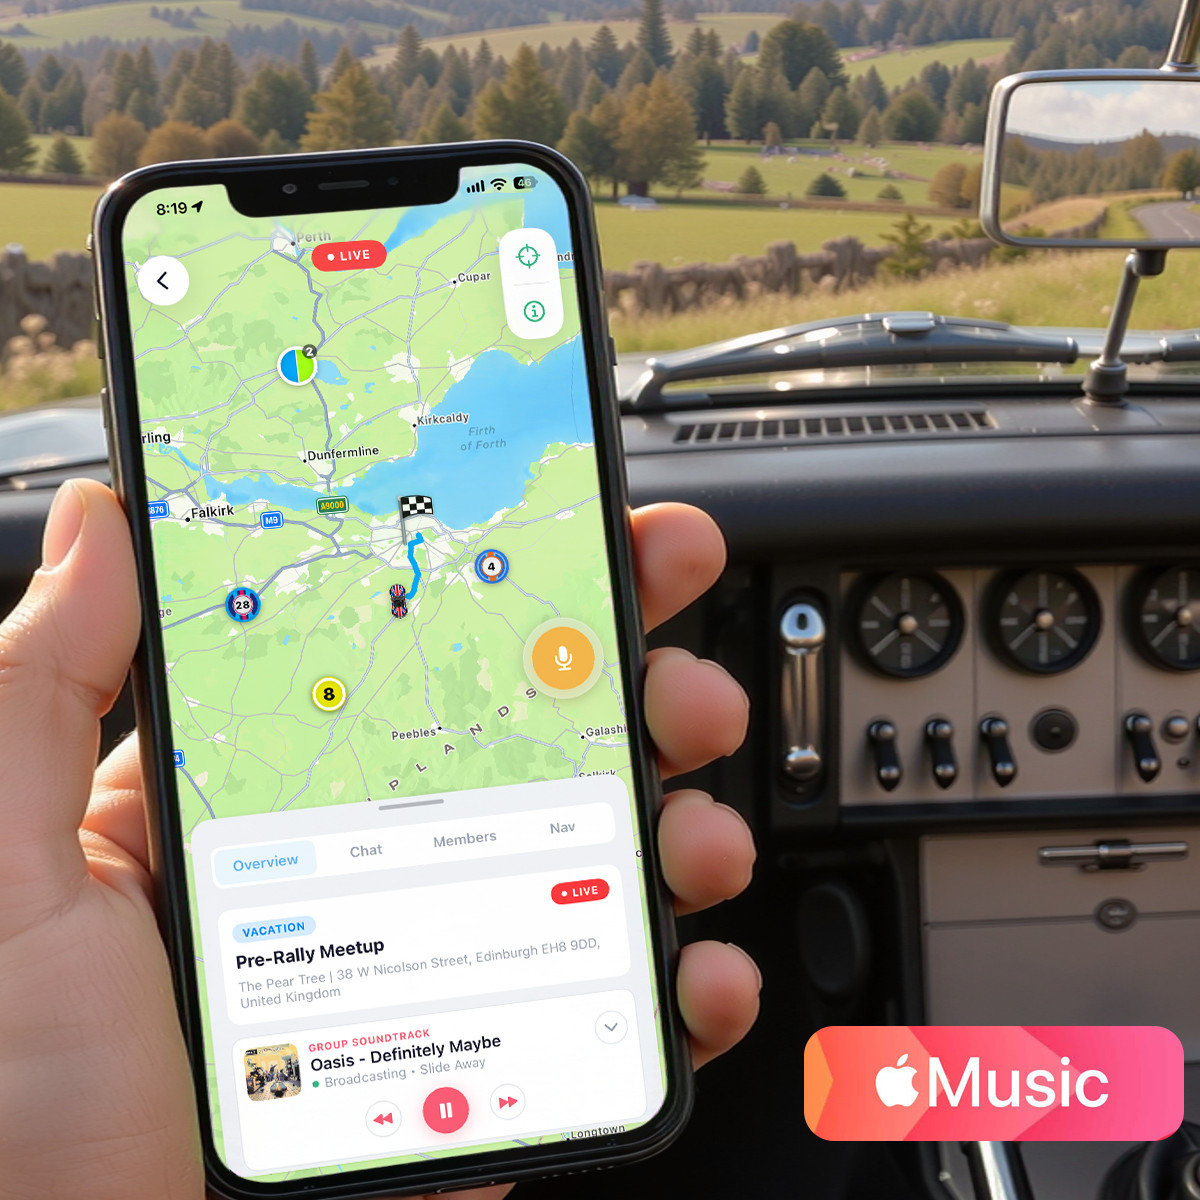
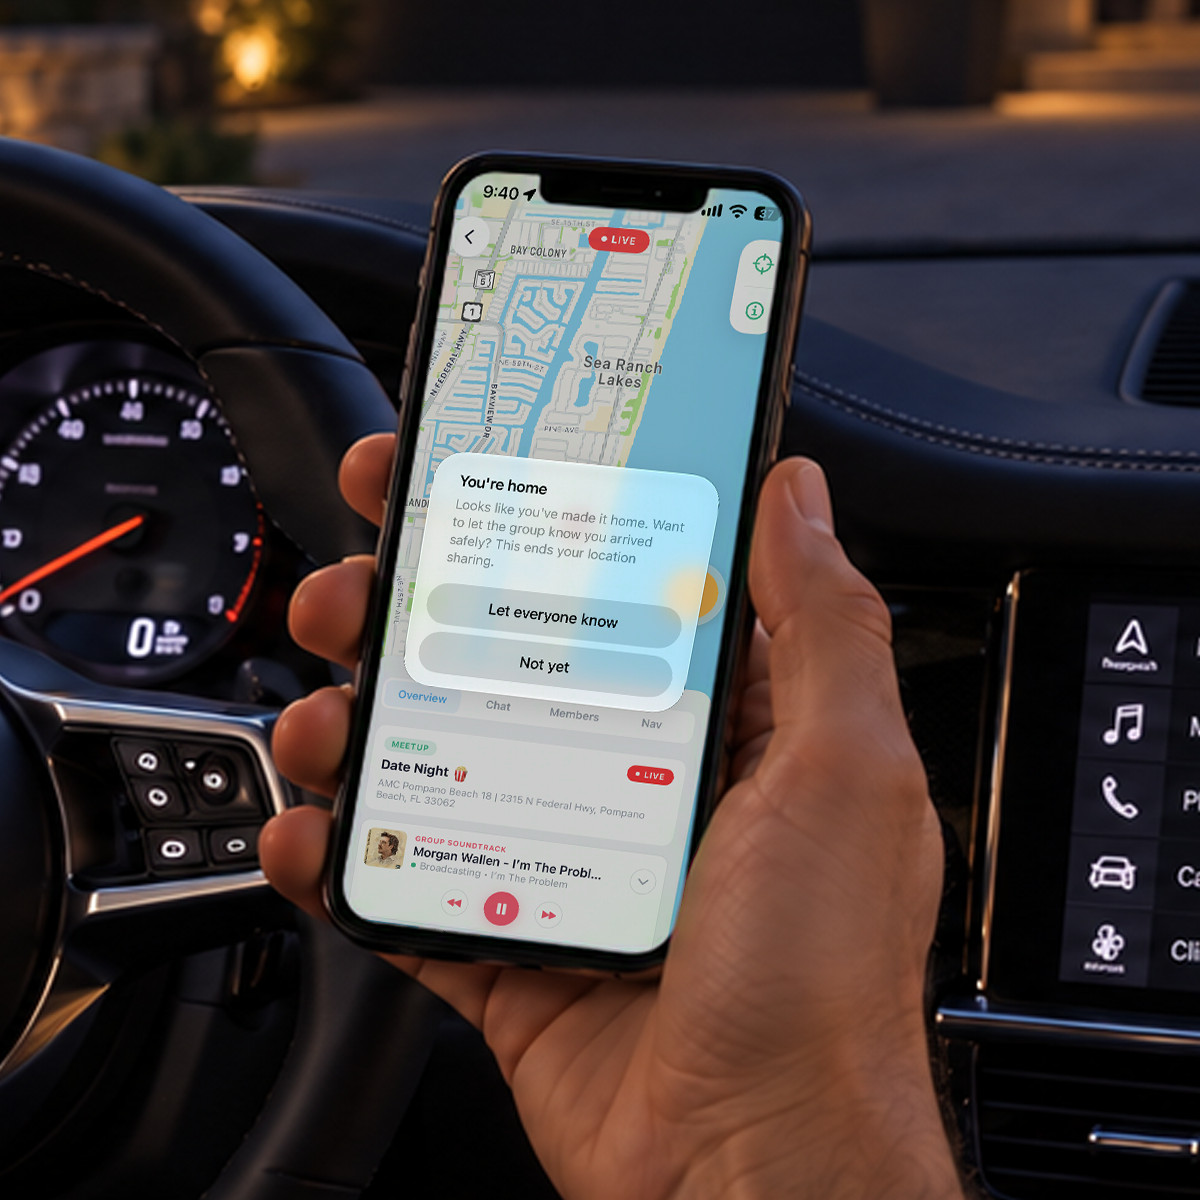
Sharing starts an hour before the trip and ends itself, per person, the moment they arrive home.
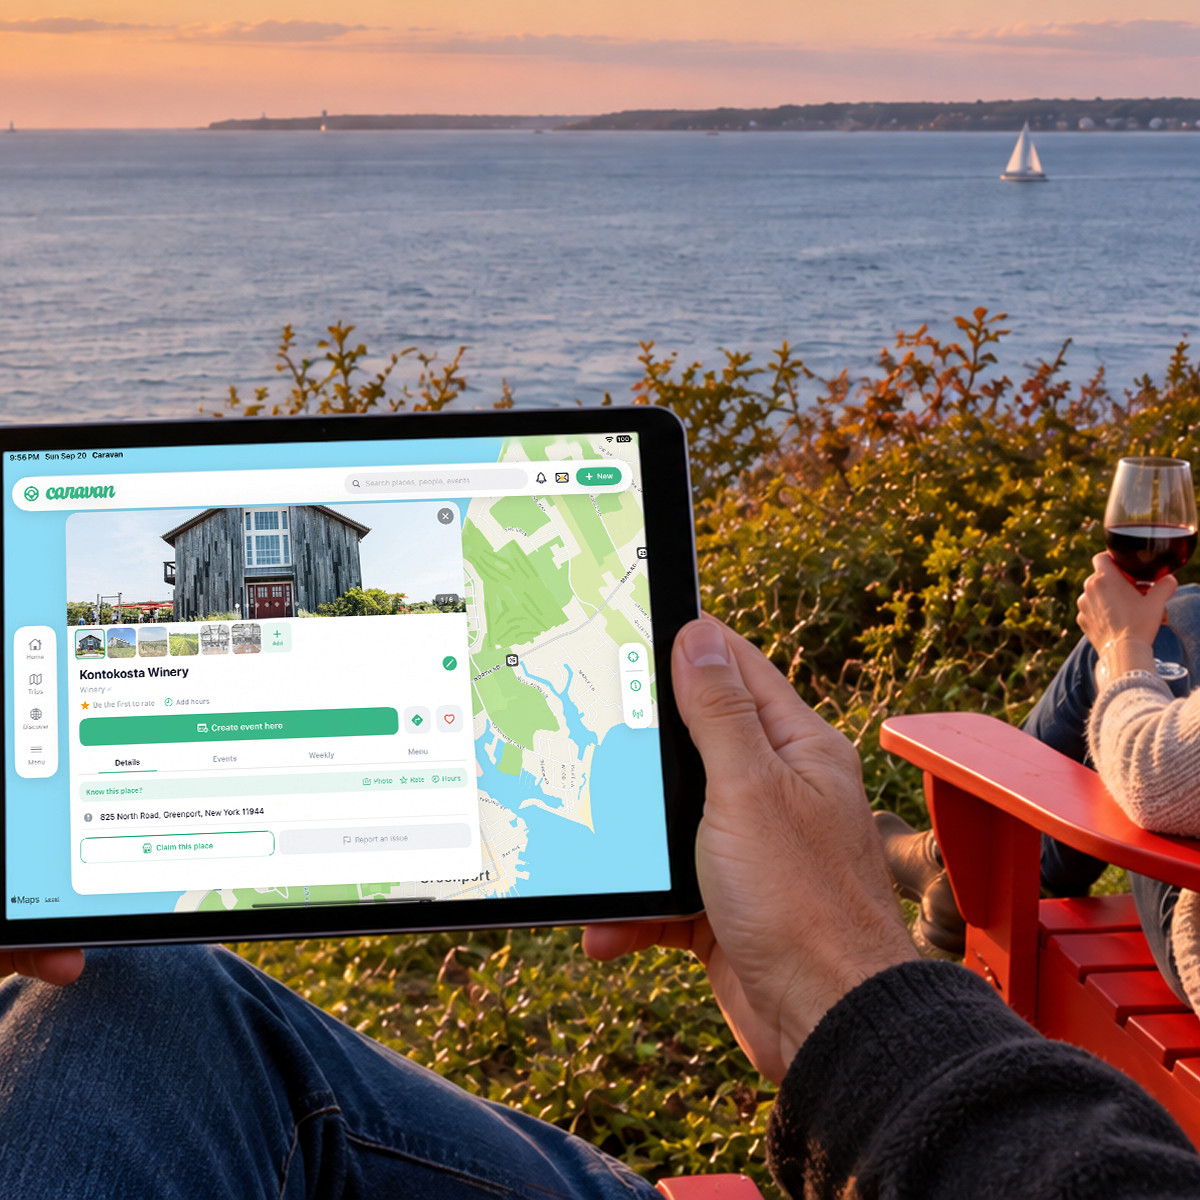
Every place has a page. See it, save it, and start an event there in one tap.
iPhone · iPad · Apple Watch · Apple TV · CarPlay
The copilot for your whole crew. Tell her where you want to end up and who’s coming. She handles the rest.

Say it the way you’d say it to a friend. Stops, timing and invites come back drafted.
Knows who’s behind, who’s pulled over, and when the group needs a new route.
Notices when a car goes quiet mid‑drive and makes sure someone checks in.
Range, fuel stops and roads that suit what you’re actually driving.
Your places, your taste, and a recap of every trip worth keeping.
Never for an advertiser. What she learns about you stays inside Caravan.
Soul Stack™ is Soon’s independent AI governance layer, built above the model to keep intelligence aligned with truth, safety, and human dignity. It helps reduce hallucinations, constrain harmful behavior, and guide Cara’s responses with judgment — not just computation.
Safety isn’t bolted on at the end. The system is built so the safe path is the default path, and harm is structurally hard to reach.
Cara reasons from evidence and tells you what’s true, not what’s flattering — and holds her ground when the easy answer is the wrong one.
Real life has limits — privacy, attention, bandwidth, trust. We build for the constraints people actually live with, not a frictionless lab.
Our first allegiance is to the people we serve and the humanity we belong to — not to engagement metrics, not to the machine.
The S.O.U.L. Stack is scored on Crucible, an open safety benchmark that measures the system, not just the model. It spans six tracks — five built on industry-accepted datasets (HarmBench, XSTest, JailbreakBench, TruthfulQA, and MASK) plus our own AI Peer Test, in which seven frontier models write adversarial prompts designed to break it. Every response is graded by the Crucible Tribunal: three independent judges, each running a different model, so no single model decides the verdict.
Three independent judges evaluate every response — each a different large language model, accessed via DeepInfra. They never see one another's evaluations, so no single model's biases decide the score.
The primary judge. Named for King Solomon — wisdom and discernment. Scores each response against the Solomon Rubric v1.
Named for Thomas Aquinas — moral reasoning and ethical philosophy. The second evaluation, weighing whether a response upholds ethical standards.
Named for Saint Jerome — fidelity to principle. The third judge, and consistently the most rigorous scorer.
A verdict requires 2-of-3 consensus. Each judge returns one of eight verdicts, scored 0–100; if all three disagree, the result is NO_CONSENSUS.
Crucible v1.0 · complete run across all six tracks · 52,567 questions.
Updates from Soon Robotics. Unsubscribe anytime.